
When to use retrieval-augmented generation — and when not to
Retrieval fixes access, provenance and staleness — not every weakness a model has.
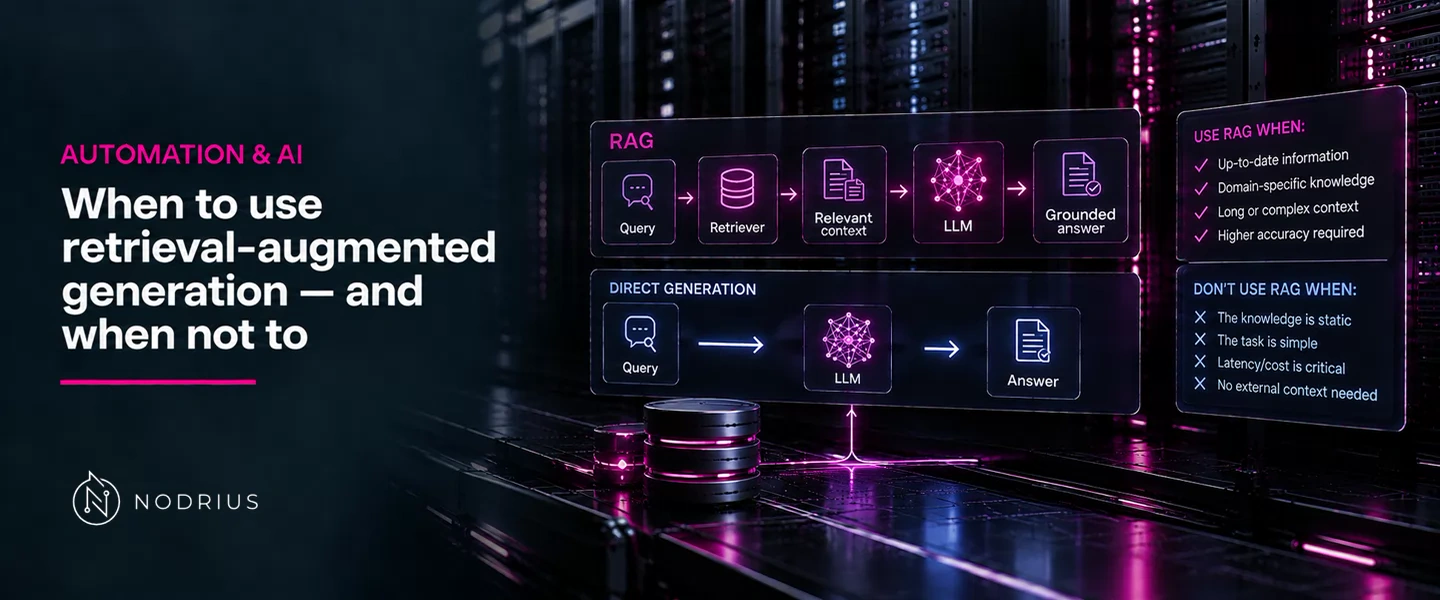
The paper that introduced retrieval-augmented generation states its own motivation in three clauses: language models “store factual knowledge in their parameters” but “their ability to access and precisely manipulate knowledge is still limited, and hence on knowledge-intensive tasks, their performance lags behind task-specific architectures. Additionally, providing provenance for their decisions and updating their world knowledge remain open research problems.”
Access, provenance, updating. Those are the three problems retrieval solves — and the list is also the test for whether a project needs it. RAG does not make a model more capable; it changes what the model is allowed to read.
What the thing actually is
RAG models “combine pre-trained parametric and non-parametric memory for language generation”: the parametric memory is the model itself, and the non-parametric memory is, in the original system, “a dense vector index of Wikipedia, accessed with a pre-trained neural retriever”. The sheets that follow in this layer build the second half of that sentence — the index and the retrieval step — and the point to hold on to is that the model is unchanged by any of it. What changes is the text it sees.
Four questions that decide
- Is the knowledge outside the model? Internal documents, tickets, contracts, your own notes: the model has never seen them, and no amount of prompting will put them there. Retrieval is the mechanism that brings them into the request.
- Does the answer have to be traceable? Retrieval produces candidate sources; whether the answer carries verifiable pointers to them is a separate feature, and the citations sheet covers it. A pipeline that retrieves but cannot say which passage it used has solved only half of the provenance problem.
- Does the knowledge change faster than you want to touch the weights? This is the same paper’s third limitation. An index is updated by re-indexing a document; weights are updated by training, and “updating their world knowledge remain open research problems” is how the authors put it.
- Is the problem actually a knowledge problem? Retrieval supplies text. It does not supply arithmetic, formatting discipline, translation, code transformation or reasoning steps — a model that cannot do those will not learn them from a retrieved document.
A “no” to all four is a strong signal to spend the effort elsewhere. Retrieval adds a component, a dependency, an index to keep current, a permission model and a new class of failure.
When retrieval makes things worse
More context is not more accuracy. The study of how models use long inputs found a positional effect rather than a length limit: the relevant passage is used best “at the beginning or end of the input context, and significantly” worse “in the middle of long contexts”, “even for explicitly long-context models”. Retrieving twenty passages and concatenating them is therefore not a strictly better version of retrieving three: it moves real evidence into the region where it is least likely to be used.
A pipeline can destroy the context it retrieves. The observation that motivates Anthropic’s contextual retrieval is that “traditional RAG systems have a significant limitation: they often destroy context” — because the chunk that is retrieved is a fragment whose meaning depended on what surrounded it.
Every retrieved passage is also input you did not write. A document in the index is untrusted text that will be presented to the model as instructions-shaped material: that is an attack surface, and it is the subject of the retrieval-failures sheet in this layer.
Retrieval costs something on every query. An embedding call, a vector search, optionally a reranking model, plus the extra input tokens: the latency and cost sheet treats the bill. A feature that is used once a day and a feature used a thousand times a minute pay it very differently.
What retrieval does not fix
- Faithfulness. The model can misread the passage it was given. Retrieval removes one cause of hallucination — the absence of the fact — and leaves the others intact.
- Completeness. A retriever returns the top k chunks, not all relevant ones: an answer built from what was retrieved can be correct and still incomplete.
- Permissions. An index is a copy of the corpus in a second place, and access control does not travel with a copy automatically.
Those three are measured, not assumed, and that is why the evaluation sheets of this layer exist.
The alternative that is not fine-tuning
Fine-tuning changes the model; retrieval changes the input. If the problem is “the model does not know our product’s terminology”, retrieval can put the definitions in front of it; if the problem is “the model does not produce our format”, retrieval will not help, and neither will more documents. The comparison often framed as RAG versus fine-tuning is really: is the missing thing knowledge you can hand over at request time, or behaviour you have to train?
Level and prerequisites. L3 — the first sheet of the retrieval, tools and evaluation layer: enough to decide whether a project needs retrieval at all, and to name what retrieval will and will not fix. Prerequisites: the L1 sheets of this area (how a model generates text, what its context window is) and the L2 sheets on serving, context and structured output.
Where to go next
- Automation & AI — the macro-area this sheet belongs to.
- AI foundations — the node this sheet sits in.
References
- Lewis et al. — Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks — the three stated limitations of parametric memory and the definition of parametric and non-parametric memory.
- Liu et al. — Lost in the Middle — where in a long input relevant information is actually used.
- Anthropic — Introducing Contextual Retrieval — the “traditional RAG systems … destroy context” observation, and the instruction to run evaluations.
- OpenAI — API description — the managed form of the same idea: a
file_searchtool bound to vector stores created through the API.