
Filters and hybrid search: combining meaning with exact terms
Dense retrieval misses exact tokens; hybrid search merges two rankings and needs a filter.
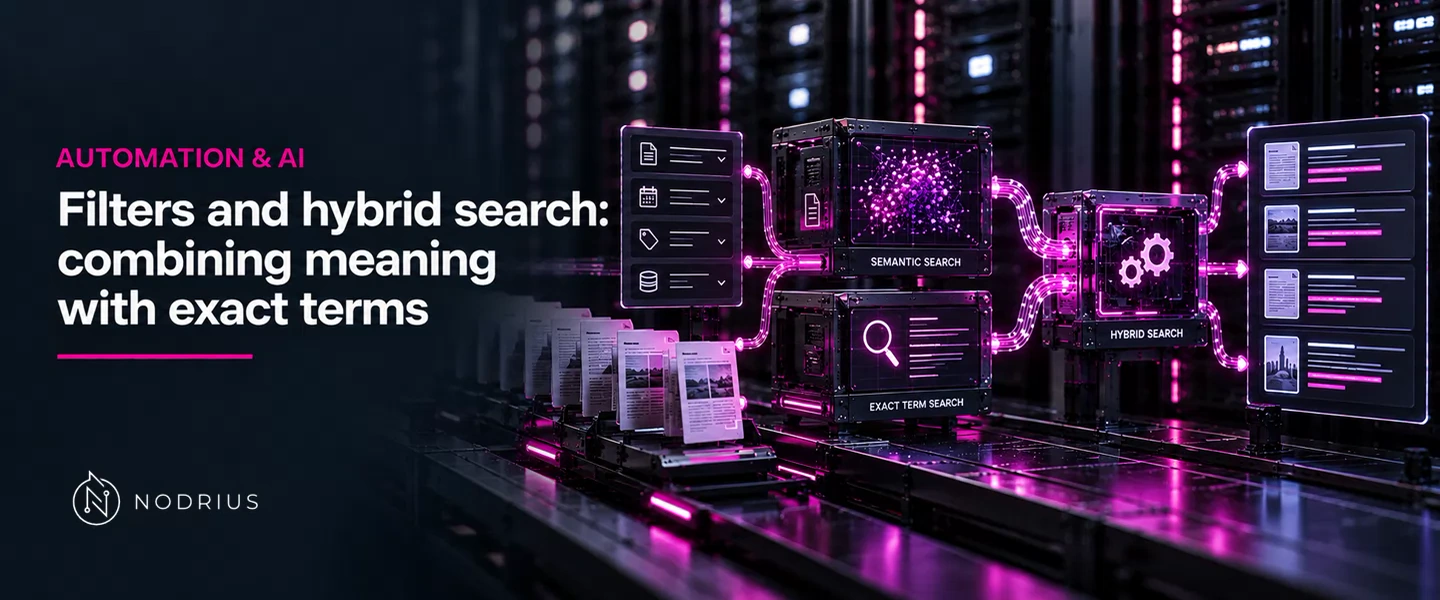
A vector search alone fails on the queries that contain a rare token, and a keyword search alone fails on the queries that use different words for the same thing. Hybrid search is the standard answer — run both, then merge — and the interesting part is not the running but the merging.
Why exact tokens break semantic search
The failure is best seen on an identifier. Anthropic’s illustration is a support query for an error code: asked about “Error code TS-999”, an embedding model “might find content about error codes in general, but could miss the” exact string, because the embedding represents meaning and an error code carries none.
Lexical matching does the opposite: it finds the token because the token is there. The classic ranking function for that job is “BM25 (Best Matching 25)”, described as building on TF-IDF while refining it with document length and other factors. It is old, unfashionable and extremely hard to beat on the queries that matter most in operations: names, codes, versions, identifiers, quoted phrases.
What hybrid search is
The store documentation puts it in one sentence: “Hybrid search combines the results of a vector search and a keyword (BM25F) search by fusing the two result sets.” Two details follow immediately.
The balance is a parameter, and it is not neutral by default. In one implementation the knob is alpha:
“An alpha of 1 is a pure vector search. An alpha of 0 is a pure keyword search.” — and, importantly, “If you
do not set alpha, the effective weighting depends on your client”, which means the same query can be answered
differently by two clients against the same data.
Fusion is a method of its own. The approach designed to avoid score comparability problems is reciprocal rank fusion: “Reciprocal rank fusion (RRF) is a method for combining multiple result sets with different relevance indicators into a single result set. RRF requires no tuning, and the different relevance indicators do not have to be related”. It merges by rank rather than by score, which is why it needs no tuning: the number that comes out of a lexical search and the number that comes out of a vector search are not the same kind of quantity, and adding them is not meaningful. The fusion has its own parameters (a rank constant) and its own precondition — at least two child retrievers.
Filters are part of the query, not a clean-up step
Every real retrieval query carries conditions that are not “semantically similar”: the document must belong to
this tenant, be effective at this date, be in this language, be a policy rather than a draft. In the stores
that implement filtering properly, those conditions are expressed as a structured filter alongside the query —
the reference implementation exposes the familiar boolean vocabulary, where must behaves as an AND and
should as an OR over conditions.
Two properties matter at L3:
- Performance depends on indexing the fields you filter on. “For performant filtering, create payload indexes for the fields you plan to filter on. For best results, create payload indexes before ingesting data.” A filter over an unindexed field is a scan, and a scan inside a search is where latency surprises come from.
- A filter changes the search, not the results. Whether filtering happens before or after the approximate search changes both quality and cost. A highly selective filter applied before an approximate search leaves it fewer candidates to work with, which is the interaction described in the previous sheet; filtering after the search can leave too few results to fill the answer.
The distinction between the two kinds of filter matters for the rest of this layer: a relevance filter (narrowing the corpus to what the user asked about) is a ranking decision, while a permission filter is a correctness decision and cannot be left to the query’s semantics — the access-control sheet treats it as such.
What hybrid search costs, and how to decide
The costs are concrete: a second index to build and keep in sync, a second query per request, a fusion step, and a weighting parameter that has to be chosen. None of them is large, and none of them is free.
The decision rule is unglamorous but effective:
- Do users search for codes, names, identifiers, quoted strings? Then lexical matching is mandatory — a pure vector pipeline will fail precisely on the queries that are unambiguous.
- Do users ask conceptual questions where the words they use are not the words in the documents? Then dense retrieval earns its place.
- Both in the same product is the normal case, which is why hybrid search is the default shape of a serious retrieval step.
- The weight is then a parameter to be measured, not argued: a test set with queries whose right answers are known will show whether the lexical or the semantic channel is carrying the result (the evaluation sheets of this layer describe the set).
Level and prerequisites. L3 — integration level: the reader must be able to specify a hybrid retrieval step, including which filters belong to the query and how the two rankings are merged. No store is configured and no weight is tuned here. Prerequisites: the embeddings and vector-index sheets of this layer.
Where to go next
- Automation & AI — the macro-area this sheet belongs to.
- Applications — the node this sheet sits in.
References
- Anthropic — Introducing Contextual Retrieval — the “Error code TS-999” example and the BM25 explanation.
- Weaviate — Hybrid search — the definition of hybrid search, the configurability of fusion and weights,
and the
alphasemantics. - Elasticsearch — Reciprocal rank fusion — the definition of RRF, the no-tuning property, the rank constant and the two-retriever precondition.
- Qdrant — Filtering — the filter vocabulary and the payload-index requirement.