
Short-term and long-term memory in LLM systems
A finite context window forces every LLM system to decide what to remember.
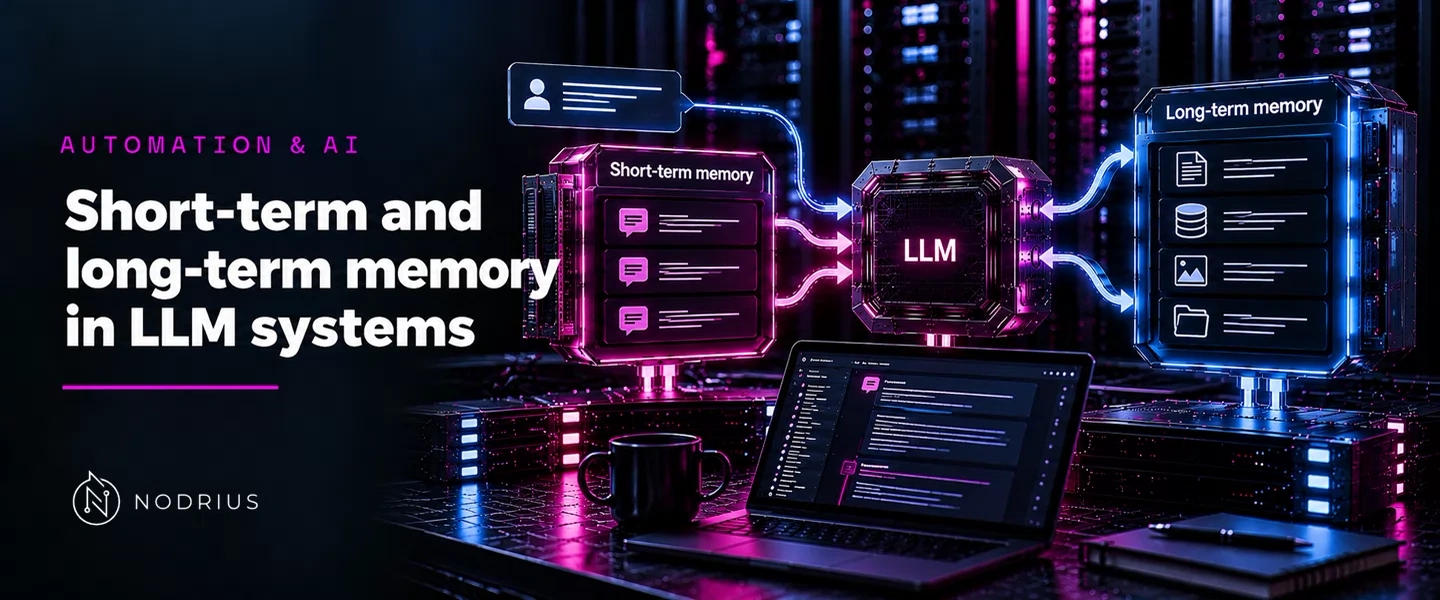
An LLM has no memory of its own. Each response is computed from the prompt tokens it is handed at that moment; when the response ends, nothing stays inside the model. Every memory an LLM-based system appears to have is text the system assembled and placed into the context window — and that window is finite.
Memory in LLM systems is therefore not a model feature but a design layered around the model: what stays inside the current context window for one thread, and what is kept outside and recalled later. MemGPT uses the vocabulary of an operating system and “delineates between two primary memory types: main context (analogous to main memory/physical memory/RAM) and external context (analogous to disk memory/disk storage)”. The analogy is the useful part: the window is RAM — fast, small, volatile — and long-term memory is disk.
The context window is the only memory the model has
Main context is made of prompt tokens; “anything in main context is considered in-context and can be accessed by the LLM processor during inference”, while external context “is held outside of the LLMs fixed context window” and enters inference only if moved in. MemGPT states the motivation plainly: LLMs are “constrained by limited context windows, hindering their utility in tasks like extended conversations and document analysis”. Short-term and long-term memory name the two sides of that boundary.
Short-term memory: the working context of one thread
Short-term memory is whatever must sit in the window to answer the next turn: the running history of one conversation. The vendor documentation states the reason — “AI applications need memory to share context across multiple interactions” — and the bound: “Most LLMs have a maximum supported context window (denominated in tokens).”
MemGPT splits its prompt into system instructions, a working context that is “a fixed-size read/write block of unstructured text”, and a message queue, because “The FIFO queue stores a rolling history of messages”. As the queue fills, entries are evicted and compressed: “The first index in the FIFO queue stores a system message containing a recursive summary of messages that have been evicted from the queue.” The usual levers — trim old messages or summarise them — are both lossy: “you may lose information from culling of the message queue”.
Long-term memory: what you keep outside the window
Long-term memory is data held in a store rather than in the prompt. The pattern is described as “Use long-term memory to store user-specific or application-specific data across conversations” — keyed to a user or application, surviving the session, fetched only when relevant. In MemGPT the same external context is archival and recall storage: evicted messages “are stored indefinitely in recall storage and readable via MemGPT function calls”. What to store and fetch is not fixed in code — “Memory edits and retrieval are entirely self-directed”.
This is not the model’s weights. Long-term memory is external text the system chooses to inject, so whether it is a table, a key-value store or a vector index is an implementation detail; the store can be searched “by semantic similarity”.
What comes back: retrieval decides what a memory is worth
A store that holds everything is useless if the window holds little, so recall is a ranking problem. Generative agents call their long-term store a memory stream, “a long-term memory module that records, in natural language, a comprehensive list of the agent’s experiences”, and rank it: “A memory retrieval model combines relevance, recency, and importance”. Recency favours “memory objects that were recently accessed”; importance “distinguishes mundane from core memories”; relevance favours “memory objects that are related to the current situation”. Only the survivors go forward: “The top-ranked memories that fit within the language model’s context window are included in the prompt.”
Long-term memory can also be compressed before storage. The same architecture adds reflection: “We introduce a second type of memory, which we call a reflection. Reflections are higher-level, more abstract thoughts generated by the agent.” Reflection folds many observations into fewer summaries.
Limits and failure modes
The whole record never fits, and pretending otherwise hurts. Generative agents note that “the full memory stream can distract the model and does not even currently fit into the limited context window” — which is why retrieval, not completeness, is the goal. Retrieval also fails: in their evaluation, “the most common errors arose when the agent failed to retrieve relevant memories, fabricated embellishments to the agent’s memory”. Trimming and summarising both discard text.
Two further points are framing rather than measurement. Anything recalled is text placed in the prompt, so it inherits the trust problem of any input the system did not author; anything made durable can go stale, contradict a later fact, or carry data that was never meant to persist. Short-term and long-term memory are therefore two engineering problems — fitting a bounded window, and deciding what deserves to outlive it.
Level and prerequisites. L4 — the model is finished and the system around it is not: the reader must reason about where memory lives, what moves it into the window, and what is lost. Prerequisites: the L1 sheets on text generation and the context window, and the L2 sheets on context management and serving.
Where to go next
- Automation & AI — the macro-area.
- Applications — the node for this sheet.
References
- Packer et al. — MemGPT: Towards LLMs as Operating Systems — the main-context / external-context split, the working context and message queue, self-directed retrieval, and the motivation from limited context windows.
- Park et al. — Generative Agents: Interactive Simulacra of Human Behavior — the memory stream, the recency/importance/relevance retrieval ranking, reflection, and the observed retrieval failure modes.
- LangChain — Memory (LangGraph documentation) — the short-term (thread-level) and long-term (cross-conversation) distinction, the context-window limit, trimming versus summarising, and semantic search over the store.