
State, checkpoints and resuming after a failure
Agent state as a checkpoint: what survives a crash, and what re-runs on resume.
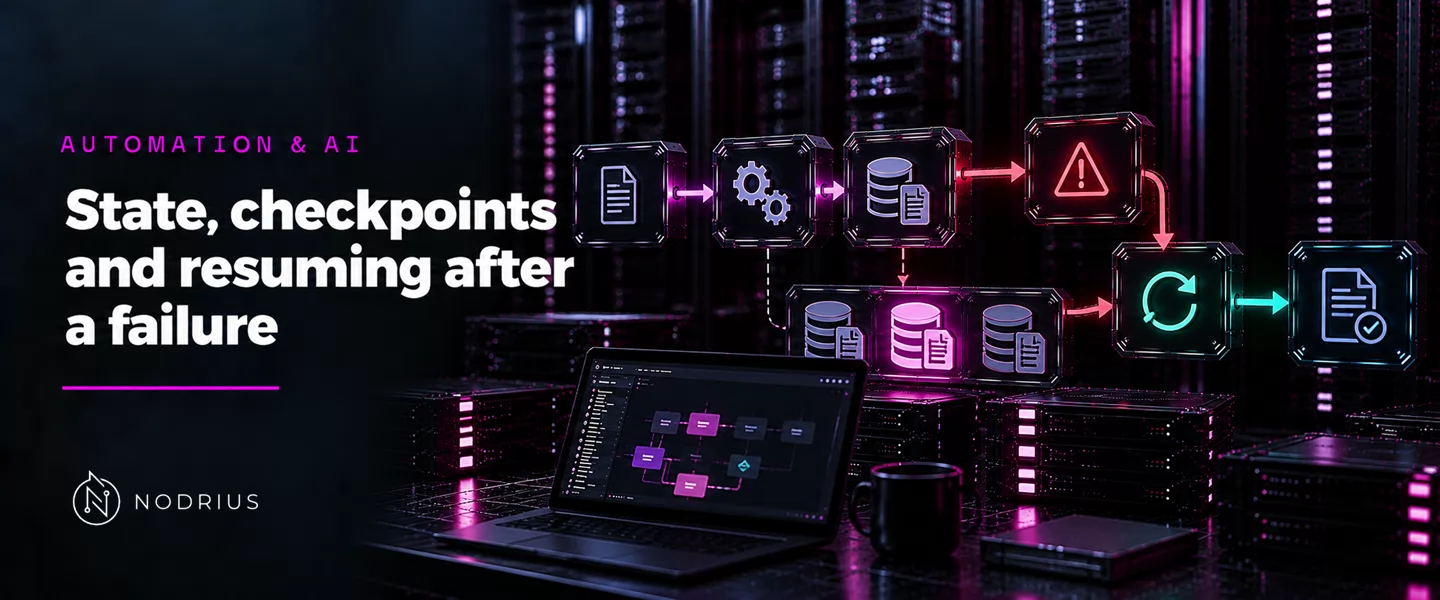
An agent run is not one call but a sequence of steps, and the data that must survive from one step to the next is its state. The purpose is stated in one sentence in the vendor documentation: persistence lets an application “keep useful information beyond a single graph run. It matters when an agent needs to continue a conversation, resume after an interruption, recover from a failure, or remember information across interactions” (Persistence, line 79).
A checkpoint is a saved snapshot of that state, written at a known step, so a later run can start from it. This sheet covers the mechanism: what gets written, under which pointer, and what happens when execution resumes.
What “state” means in an agent run
State is everything the run must carry between steps — the message history so far, the results of tool calls, a plan, and any working data a node produced. It is not the model’s context window: the window is transient and rebuilt on every call, while the state is the durable record the runtime owns.
The scoping device is the thread. Checkpointers “persist a thread’s graph state as checkpoints”, used for “short-term, thread-scoped memory, including conversation continuity, human-in-the-loop workflows, time travel, and fault tolerance” (Persistence, line 81). A second mechanism, the store, keeps “application-defined data outside the graph state” for “long-term, cross-thread memory” (line 82). What should be remembered across sessions is the memory sheet’s subject; this sheet stays with the thread-scoped half.
Checkpoints and the thread pointer
A checkpointer writes a snapshot at each step and files it under an identifier. In LangGraph that
identifier is the thread_id passed in the run configuration, and it alone decides where a later run
continues: “The thread_id you choose is effectively your persistent cursor. Reusing it resumes the same
checkpoint; using a new value starts a brand-new thread with an empty state” (Interrupts, line 92). The
same page names the mechanism directly — “thread_id is your pointer … to tell the checkpointer which
state to load” (line 90). Because each snapshot is addressable, the run’s history can be inspected without
re-deriving it from logs.
Resuming after a pause or a failure
Resuming is one operation whether the run stopped for a human decision or because the process died. The mechanism saves before it continues: “When an interrupt is triggered, LangGraph saves the graph state using its persistence layer and waits indefinitely until you resume execution” (Interrupts, line 86). The sentence to keep: “Checkpointing keeps your place: the checkpointer writes the exact graph state so you can resume later, even when in an error state” (line 89).
A managed platform can offer the equivalent server-side: the OpenAI Agents SDK states that “conversationId and previousResponseId are run-time controls, not Agent constructor fields” (Agents SDK, line 1236). Either way, a durable identifier names the state, and the next run is handed that identifier.
The resumed step does not restart where it stopped
The subtle cost of checkpointing is how resumption treats the code inside a step. A resumed step does not pick up at the line after the pause; it re-runs: the runtime “restarts the entire node from the beginning—it does not resume from the exact line where interrupt was called. This means any code that ran before the interrupt will execute again” (Interrupts, line 550).
Everything before a save point is therefore part of the durability contract. A step with side effects — writing a record, sending a message, charging a card — repeats them, which is why the same page warns that “side effects called before interrupt should (ideally) be idempotent” (line 669). The rule: save the checkpoint before the effect, or make the effect safe to apply twice.
Checkpoints are a baseline you can roll back to
The idea predates agents. A security configuration-management guide defines a baseline configuration as specifications “that has been formally reviewed and agreed on at a given point in time, and which can be changed only through change control procedures” (NIST SP 800-128, lines 1254–1255), with older approved versions “maintained and made available for review or rollback as needed” (lines 1267–1268). When a release misbehaves, “retention of previous versions allows for a rollback or restoration to a previous secure and functional version” of the baseline (lines 2883–2884). A checkpointed agent is that discipline at run granularity: a known-good state a run can restart from.
Two operational limits follow. Not every store is durable: “MemorySaver and InMemorySaver store checkpoints in RAM. When the process restarts, all checkpoints are lost” (Persistence, line 117). And they accumulate: “Over long conversations, checkpoints accumulate. This can increase latency and storage costs” (line 123), so retention or pruning is a deployment decision.
Level and prerequisites. L4 — the reader must reason about the durability contract of a running system: which state survives a crash, under which pointer it is found, and why a resumed step re-executes. Prerequisites: the L4 sheets on the action loop and on tool schemas (the step being checkpointed), the L4 sheet on short- and long-term memory, and the L2 sheets on serving and structured output.
Where to go next
- Automation & AI — the macro-area this sheet belongs to.
- Applications — the node this sheet sits in.
References
- LangChain — Persistence — the thread-scoped checkpointer and its limits: in-memory stores and unbounded checkpoints.
- LangChain — Interrupts — the resume contract: saved state, the thread pointer, and the restart-from-the-beginning behaviour.
- NIST — SP 800-128 — the baseline-configuration and rollback discipline that a checkpoint mirrors.
- OpenAI — Agents SDK guide — conversation state as a run-time pointer rather than a static field.